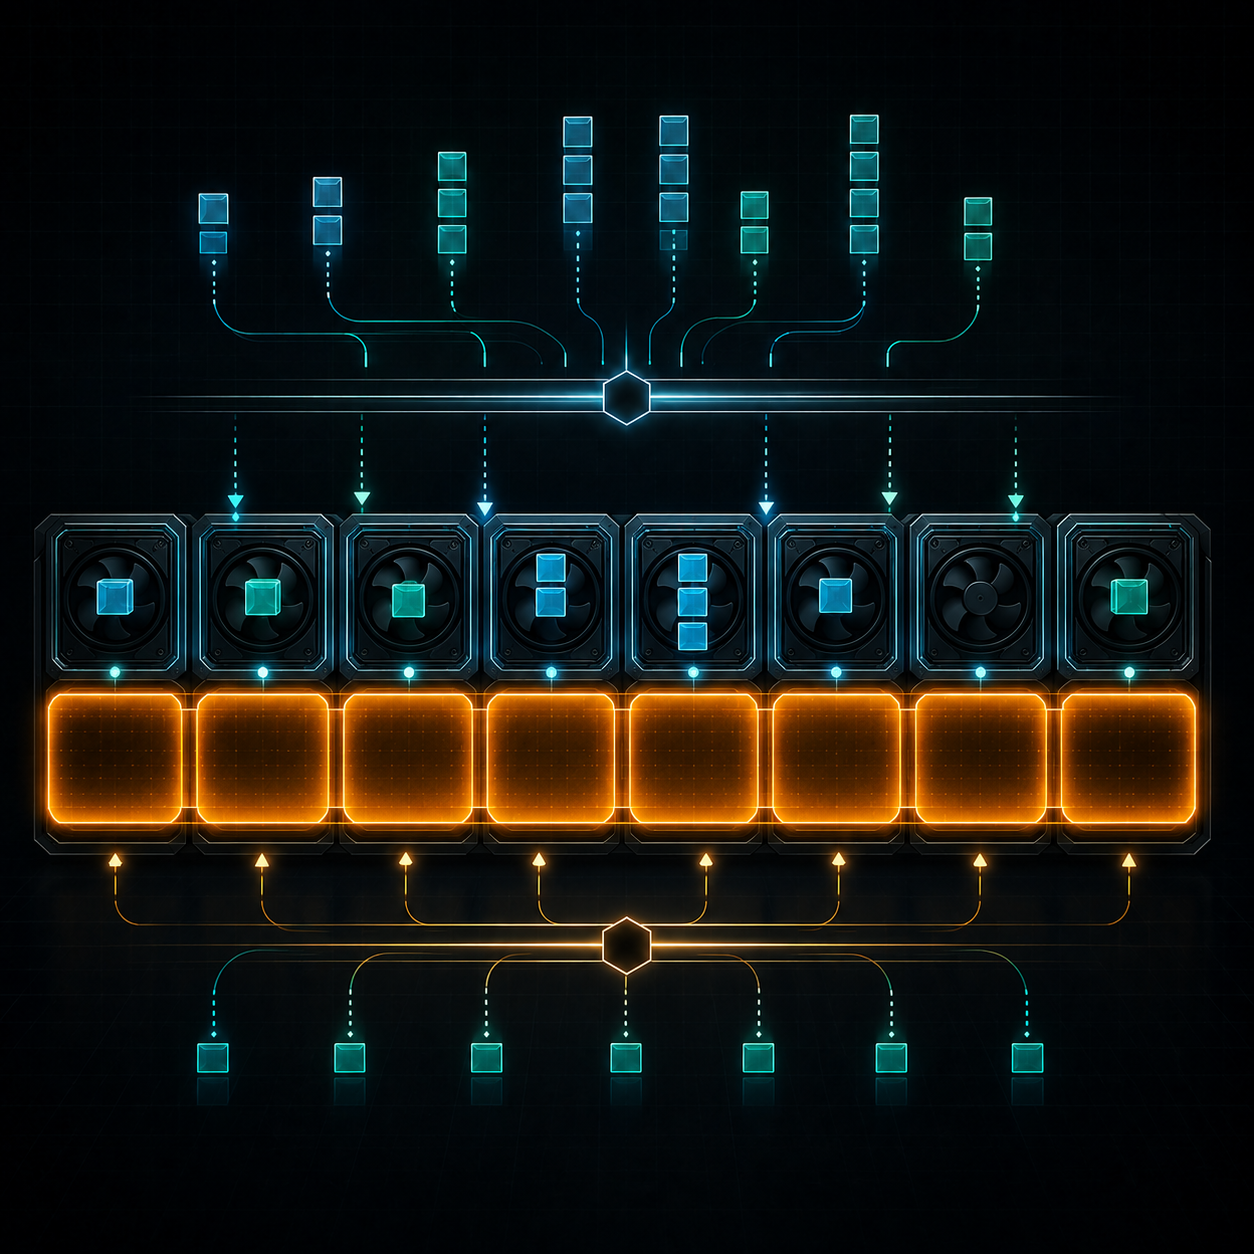
The resource pool is simple. The queueing geometry is not.
Imagine a single inference node with eight GPUs. Small-model requests need exactly one GPU, so eight can run independently. Large-model requests use tensor or pipeline parallelism and must acquire all eight GPUs simultaneously. They cannot start on seven. They cannot share the node while running.
Small jobs compose naturally: every free GPU is useful immediately.
Large work is gang-scheduled: partial allocation has no value.
The allocator therefore faces two different notions of availability. A small request asks, “Is any GPU free?” A large request asks, “Is the entire set free at the same instant?” That second predicate turns an ordinary worker pool into a coordination problem.
Keeping every GPU busy can make the system less useful.
The tempting policy is greedy: whenever a small request and a GPU are available, start the request. It maximizes instantaneous utilization. It can also starve every large request forever.
Suppose eight small jobs are running. One finishes, freeing GPU 3. If another small job immediately takes GPU 3, the node remains fragmented. Repeat this under continuous arrivals and there may never be a moment when all eight GPUs are free—even though individual GPUs complete work constantly.
This is a reservation paradox: work conservation at the single-GPU level destroys liveness at the whole-node level. Priority alone does not fix it if priority is consulted only when resources are already available. The scheduler must influence future admissions before the requested shape becomes available.
A large request is not starved because it loses an allocation decision. It is starved because the scheduler never allows its eligibility condition to become true.
Close the gate, then let the machine drain.
The liveness mechanism is a gate. As soon as the large queue becomes non-empty, the scheduler stops launching new small work. Small requests already running are not killed; they finish normally. Each completion returns one GPU to the free set, and that GPU remains intentionally idle. When the eighth GPU returns, the large request starts atomically.
up to 8 concurrent
CLOSES
no new small work
RESERVE
all 8 exclusive
if large_queue:
    if running_jobs:
        return []                 # drain; admit nothing
    large = large_queue.pop_left()
    return reserve(large, ALL_GPUS)

while small_queue and free_gpus:
    small = small_queue.pop_left()
    reserve(small, one_free_gpu)
The deliberate idleness during drain is not wasted capacity. It is capacity being assembled into the only shape that can run the waiting job. This is the same reason memory compactors, gang schedulers, and maintenance quiescence mechanisms temporarily refuse otherwise valid work.
If small runtimes are bounded, so is the drain: a newly waiting large request waits at most the maximum remaining runtime among small jobs already in flight. New small arrivals cannot extend that interval.
Writer preference solves one starvation problem—and can create its mirror image.
Strict large priority is sufficient to protect large requests from small traffic. But if large requests also arrive continuously, blindly draining one large job into the next can starve the small queue. A scheduler advertised as “fair” should explain which direction fairness flows.
The implementation uses phase fairness. After a large request completes, if both queues contain work, the scheduler admits one wave of at most eight small requests. The admission gate closes again immediately; when that wave drains, the next large request runs. Each class therefore makes bounded progress.
≤ 8 jobs
≤ 8 jobs
A subtle detail matters: fairness credit cannot linger forever. If a large job ends and small jobs receive unrestricted service because no large request is waiting, that service consumes the credit. Otherwise a later large arrival could pay for an unnecessary extra small wave after it has already waited for active small jobs to drain.
| Mode | Between consecutive large jobs | Best for |
|---|---|---|
| Phase fair | One bounded small wave when small work waits | Mixed multi-tenant traffic |
| Strict large | No small wave while a large request waits | Latency-critical large models |
Make scheduling decisions in one place; execute work somewhere else.
The open-source implementation is intentionally dependency-free and compact. It maintains two FIFO queues, a set of free GPU IDs, a map of running jobs, and a condition variable guarding every state transition. One dispatcher thread decides admission. Worker threads execute callbacks only after reservation is committed.
That separation is important. The scheduling policy should not know whether the callback invokes PyTorch, vLLM, TensorRT-LLM, a subprocess launcher, or an RPC endpoint. Its contract is smaller: choose a legal allocation, hand the exclusive GPU IDs to the runtime, and reclaim them exactly once.
with GPUScheduler(gpu_count=8) as scheduler:
    future = scheduler.submit(
        "small",
        lambda gpu_ids: model.generate(
            prompt="hello",
            devices=gpu_ids,
        ),
    )
    result = future.result()
Reservation occurs under the condition lock before the worker starts. Completion releases GPUs inside a finally block, making model failure a job outcome rather than a capacity leak. Snapshots expose queue depths, running counts, free GPU IDs, and completed, failed, and cancelled counters.
The invariants are the architecture
- Free and allocated GPU sets are disjoint.
- Allocations of distinct running jobs never overlap.
- A small allocation contains exactly one GPU.
- A large allocation equals the complete configured GPU set.
- If a large job runs, no other job runs.
Everything else—the API, CLI, HTTP adapter, and metrics—is built around preserving those five facts across concurrent submissions and failures.
The dangerous race fits between “queued” and “running.”
Cancellation looks easy until a future is cancelled at the same moment the dispatcher removes its job from the queue. If the scheduler reserves GPUs without atomically claiming execution ownership, the caller may observe successful cancellation while the callback still runs. When the callback later publishes a result, the future is already terminal.
The implementation closes this gap with Future.set_running_or_notify_cancel() while holding the scheduler lock. Exactly one outcome wins: cancellation prevents reservation, or reservation marks the future running and later cancellation fails. There is no state where GPU work runs behind a cancelled contract.
Resource reservation and ownership transfer must be one logical transition. “Pop, then mark running later” is two transitions with a race in between.
The same discipline applies to completion. State becomes succeeded or failed, counters update, GPU IDs return to the free set, the running map is cleared, and the dispatcher is notified under one lock. User code never runs while that lock is held.
Fairness claims need adversarial timelines, not happy-path unit tests.
The repository’s tests coordinate jobs with events rather than relying on arbitrary sleeps. Eight small callbacks are held in flight to prove distinct assignment. A large request and a late small request are then queued; releasing the first wave must start the large request while the late small remains blocked. Only after the large releases all eight GPUs may the late small begin.
A second test runs two large requests with a queued small request between them. The small request must run as a bounded wave before the second large request. Another regression test proves that unrestricted small service consumes stale fairness credit. Failure and cancellation tests verify that every GPU returns to the pool and cancelled callbacks never execute.
| Scenario | Required observation |
|---|---|
| 8 small jobs | Eight distinct IDs; concurrent execution |
| Large waits | Late small blocked; large receives IDs 0–7 |
| Large stream | Queued small wave advances between large jobs |
| Callback fails | All GPU capacity recovered |
| Queued cancellation | Callback never starts; accounting remains exact |
| HTTP lifecycle | Submit, observe, complete, and inspect counters |
Cross-platform CI runs the suite on Ubuntu and Windows with Python 3.10 and 3.13. The scheduler does not require GPU hardware for correctness testing because resource ownership is modeled explicitly; a real runtime adapter can be tested separately.
The algorithm is the kernel, not the whole serving system.
The included HTTP server deliberately simulates inference with a bounded duration. It makes the scheduler observable and easy to exercise, but production service requires additional layers: durable queue semantics, authentication, tenant quotas, idempotency keys, runtime deadlines, cancellation propagation, traces, Prometheus metrics, GPU health reconciliation, and process or container isolation.
Most importantly, non-preemptive fairness assumes jobs terminate. If a small callback can run forever, the drain can run forever. No queue discipline can manufacture a bounded wait behind unbounded work. Production deployments need enforced timeouts, cooperative cancellation, or safe checkpoint-and-preempt support in the runtime.
The implementation is best understood as a node-level allocator and an executable specification. It makes the hard policy explicit, keeps the runtime boundary narrow, and gives a serving stack something concrete to extend rather than another informal claim that “priority will handle it.”
The scheduler’s most powerful operation is sometimes refusing perfectly runnable work. That temporary “no” is what creates the resource shape required for the system’s next meaningful “yes.”